In 2026, the AI story stopped being only about who designs the fastest chip. The binding constraint moved one step down the stack — to memory. The most powerful accelerators now sit idle waiting for data more often than for compute, and the companies that make that memory have gone from anonymous suppliers to the industry’s price setters: Samsung says its 2027 high-bandwidth memory is sold out, SK hynix says its output is sold out through 2029, and memory makers report operating margins near 80%.
The three things that decide how fast AI actually runs are the GPU, the memory stacked next to it, and the supply chain that puts them together. Related reading: AI Chip Market Explained
What a GPU actually does in an AI data center
A graphics processing unit is a chip built for doing thousands of simple calculations at once. Training a model means multiplying enormous tables of numbers billions of times; a CPU does this a few operations at a time, a GPU thousands at a time. That is why Nvidia, AMD and Google accelerators sit at the center of every AI data center.
But a GPU is only as fast as the data it can reach. Each calculation needs weights — the numbers the model learned in training — and those weights live in memory. Every time a model generates a word, it reads a large slice of them. If memory cannot deliver fast enough, the GPU waits. In modern AI systems, feeding the chip is the hard part; the arithmetic is the easy part.
That is the problem high-bandwidth memory was invented to solve.
What HBM is — and how it works
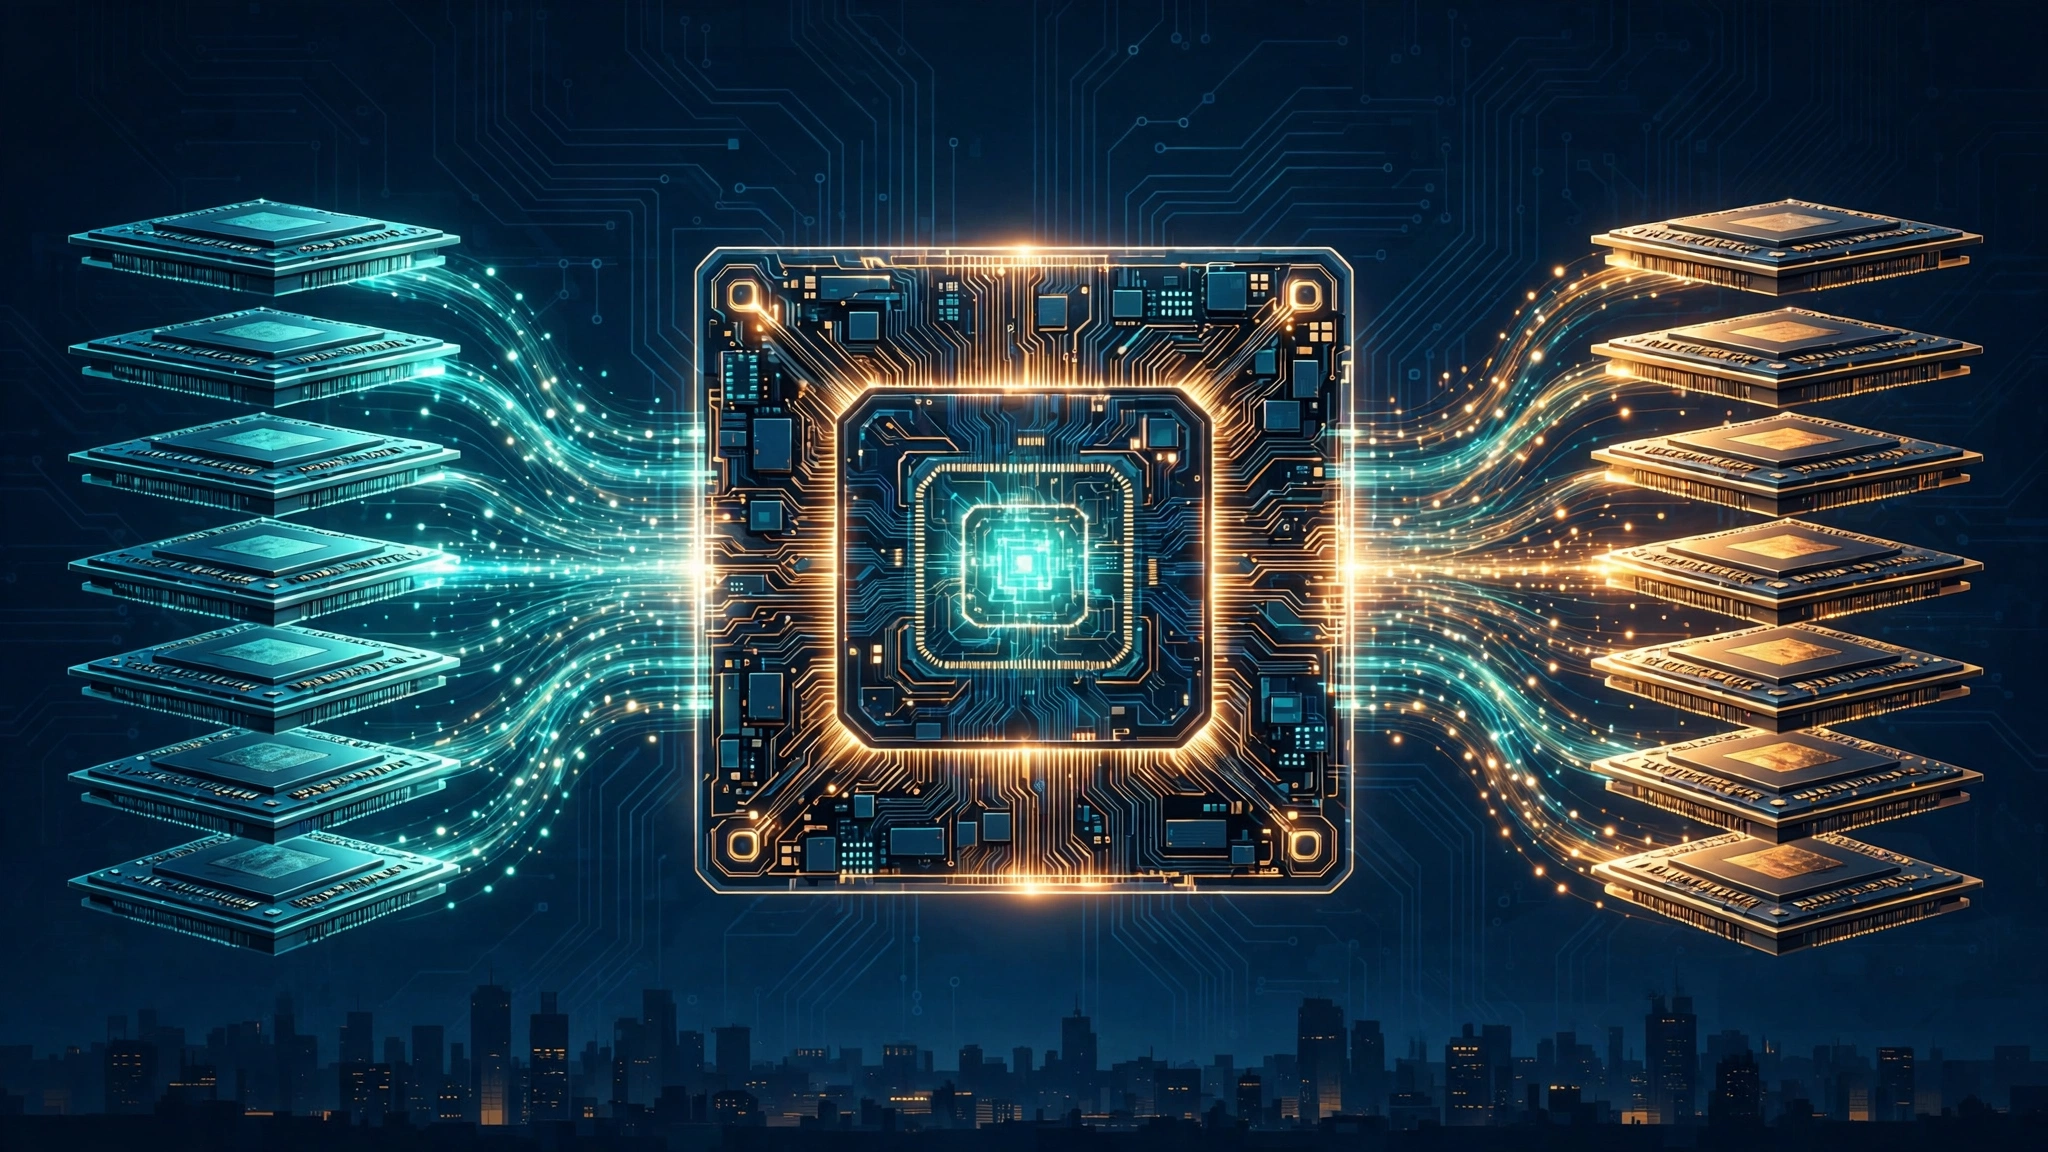
High-bandwidth memory, or HBM, is ordinary DRAM rebuilt for speed. Instead of laying memory chips flat on a circuit board, HBM stacks thin DRAM dies vertically — up to 12 or 16 high — and drills thousands of tiny vertical wires, called through-silicon vias, straight through the stack. The whole stack sits beside the GPU on the same package, connected by an extremely wide, very short link.
The width is the point: a conventional memory channel is 64 bits wide, while HBM gives each stack a 1,024-bit interface through HBM3E and HBM4 doubles that to 2,048 bits across 32 independent channels. Bandwidth is pin speed times interface width, divided by eight: at HBM4’s 8 Gb/s baseline, one stack moves 2 TB/s.
Compare that with the memory in a server. One HBM4 stack at the JEDEC baseline carries about 3.3 times the bandwidth of a full 12-channel DDR5-6400 server socket, which manages roughly 614 GB/s. That is why AI accelerators use HBM: nothing else moves data fast enough.
The trade-off is cost: HBM takes considerably more wafer area per bit than conventional DRAM, so every HBM stack shipped takes capacity away from the memory in PCs, phones and ordinary servers — the root of the shortage now rippling through the whole memory market.
HBM generations at a glance
| Generation | Interface per stack | Pin speed | Bandwidth per stack | Capacity per stack | Status |
|---|---|---|---|---|---|
| HBM3 (JEDEC, 2022) | 1,024-bit, 16 channels | Up to 6.4 Gb/s | Up to 819 GB/s | Up to 24 GB (12-high) | Shipping since 2022, in Nvidia H100 |
| HBM3E (vendor parts, 2024) | 1,024-bit | Up to 9.2 Gb/s | About 1.2 TB/s | 24–36 GB (8/12-high) | Volume through 2025, still the workhorse |
| HBM4 (JEDEC baseline, 2025) | 2,048-bit, 32 channels | 8 Gb/s | Up to 2 TB/s | Up to 64 GB (16-high) | Standard published April 16, 2025 |
| HBM4 (vendor parts, 2026) | 2,048-bit | 10–13 Gb/s | 2.8–3.3 TB/s | 36 GB (12-high) | In volume: Samsung, Micron, SK hynix |
| HBM4E (samples, 2026) | Not stated | 14–16 Gb/s | Up to 3.6 TB/s | 48 GB (12-high) | Samsung shipped samples May 29, 2026 |
HBM4 is the largest step in the technology’s history: per-stack bandwidth rises from 819 GB/s to 2 TB/s at the JEDEC baseline, and vendor parts reach up to 3.3 TB/s, about four times HBM3. The gain comes mostly from doubling the interface width — HBM4’s baseline pin speed of 8 Gb/s is barely above HBM3’s 6.4.
The ramp has been fast. Samsung announced HBM4 mass production on February 12, 2026; Micron began volume shipments of a 36 GB 12-high part in the first quarter; SK hynix began mass shipments in the second quarter and said on October 28 that HBM4 shipments began in earnest in the third quarter and would pass HBM3E in shipments and revenue in the fourth.
The five links in the AI chip supply chain
No single company makes an AI accelerator — the chain has five links, each controlled by different companies:
| Stage | Who controls it | What they do | 2026 bottleneck? |
|---|---|---|---|
| 1. Design | Nvidia, AMD, Google, Broadcom | Design the GPU and the memory system around it | No — designs are ready |
| 2. Logic foundry | TSMC (dominant), Samsung | Manufacture the GPU die itself | Tight, but expanding |
| 3. Memory | SK hynix, Samsung, Micron | Build the HBM stacks | Yes — sold out years ahead |
| 4. Advanced packaging | TSMC (CoWoS), ASE/SPIL | Bond the GPU and HBM together on one substrate | Yes — capacity is the constraint |
| 5. Data centers | Hyperscalers (Microsoft, Google, Amazon, Meta, OpenAI) | Buy the finished accelerators by the tens of thousands | Demand exceeds supply |
The packaging step is easy to overlook and hard to replace. Attaching HBM stacks to a GPU requires CoWoS — chip-on-wafer-on-substrate — a process TSMC dominates. Research firm Yole Group expects advanced-packaging capital spending to reach nearly $28 billion in 2026, with advanced-packaging revenue overtaking traditional packaging revenue for the first time. Related reading: TSMC/Samsung Q3 earnings
The chain is also geographically concentrated: logic in Taiwan, memory mostly in South Korea, packaging in Taiwan, customers mostly American — which is why a shortage in one link sets the pace for the whole industry.
The 2026 squeeze: sold-out memory and record margins
Three facts define the market. First, supply is gone: Samsung’s 2027 HBM output is fully sold, and SK hynix says its DRAM and HBM output is effectively sold out through 2029. Second, prices are rising everywhere else: memory makers have steered wafers toward AI customers, TrendForce forecasts fourth-quarter contract prices up 10%–15% for conventional DRAM and 15%–20% for NAND, and Micron expects the shortage to last until 2028, with memory prices roughly doubled. Third, the sellers are earning like monopolists: Micron, SanDisk and SK hynix each reported operating margins of about 80% in their latest quarters, on revenue up 328%–379% from a year earlier.
The shortage has reached beyond AI: PC makers and ordinary server buyers compete for the same wafers, and the memory crunch is now cited as a reason consumer electronics prices are rising.
Nvidia’s response is to redesign the memory itself. In August 2026 it unveiled NVHBM, a custom memory that moves the controller from the processor into the stack’s base die, claiming up to 30% more bandwidth than standard HBM4E. Nvidia has asked Samsung, SK hynix and Micron to build those base dies on TSMC’s 3-nanometer process — putting a logic foundry inside the memory stack for the first time. Volume production is expected in 2027. The Information also reported on November 6 that TSMC has begun weighing production of 3D DRAM — memory cells stacked vertically inside a single die — at Nvidia’s request. TSMC has played down the speculation and nothing is committed, but the direction is clear: the biggest buyer in the market wants more control over what it buys.
The Rubin reality check
There is a useful gap between what vendors announce and what ships, and Nvidia’s Rubin platform shows it. Rubin carries 288 GB of HBM4 per GPU at 19.2 TB/s. Each stack holds 36 GB, so 288 divided by 36 gives eight stacks — and 19.2 TB/s divided by eight gives 2.4 TB/s per stack in the production-qualified specification. That is below the 2.8–3.3 TB/s the memory makers quote for their HBM4 parts. Even Rubin’s original published specification of 22 TB/s worked out to only 2.75 TB/s per stack.
Nvidia confirmed the cut on October 29, reducing published HBM4 bandwidth by 12.7% and NVLink bandwidth by 16.7%, and framed the revised numbers as production-qualified reality rather than a capability retreat. Treat vendor headline bandwidth as a ceiling, not a promise: the number that matters is the bandwidth of the system that actually ships.
On November 5, the Nasdaq fell 5.52% and semiconductor shares dropped more than 12% — a reminder that the AI trade is priced for flawless execution. AMD’s competing Instinct MI455X lists 432 GB of HBM4 at 23.3 TB/s — more than Rubin on paper. Whether those numbers hold up in shipped systems is the question to ask about every new accelerator. Related reading: AI chip selloff
What to watch next
Four things decide what happens next. First, HBM4E sampling: Samsung shipped 12-high samples in May 2026 and SK hynix followed in June. Second, NVHBM: whether the three memory makers agree to build base dies on TSMC’s process, and whether volume production really starts in 2027. Third, 3D DRAM: whether TSMC moves from weighing the idea to committing capital, adding a fourth supplier to a three-company market. Fourth, demand: whether hyperscaler capital spending keeps growing fast enough to absorb memory at today’s prices — or whether 80% margins are the top of the cycle.
Frequently asked questions
Is HBM the same as the memory in my laptop?
No. Your laptop uses DDR memory — cheap, plentiful, and fast enough for one user. HBM is a different design: stacked dies, a much wider interface, far higher bandwidth, and far higher cost per gigabyte. It exists because AI accelerators must read hundreds of gigabytes of model weights in milliseconds, which DDR cannot do.
Who makes HBM?
Three companies make essentially all of it: SK hynix, Samsung and Micron. SK hynix led the HBM3E generation and was first to volume HBM4 shipments in 2026; Samsung was first to announce HBM4 mass production; Micron is the third supplier and the only American one. TSMC does not make HBM, but it makes base dies for some HBM4 stacks and does the advanced packaging that joins memory to GPU.
Will the shortage end soon?
Not soon. Samsung’s 2027 HBM is sold out, SK hynix’s output is effectively sold out through 2029, and Micron expects shortages until 2028. The realistic expectation is tight supply through 2027, with relief depending on how much capacity the three makers actually add.
This article is for informational purposes only and does not constitute financial advice. Data are sourced from JEDEC, vendor announcements, TrendForce and industry reporting as cited.